I build long-horizon RL environments that test whether coding agents can turn commercial real estate source materials into complete, visually faithful offering memorandums. CRE Bench combines a multi-turn tool-use harness with page-specific, rubric-based verification: the deliverable is rendered and scored, not just checked for plausible HTML.
The current working set spans eight brokerage cases, with 94 page rubrics and 4,160 atomic checks. It is a focused evaluation set within my broader work on an approximately 200K-offering-memorandum corpus, not a claim that the entire corpus has been benchmarked.
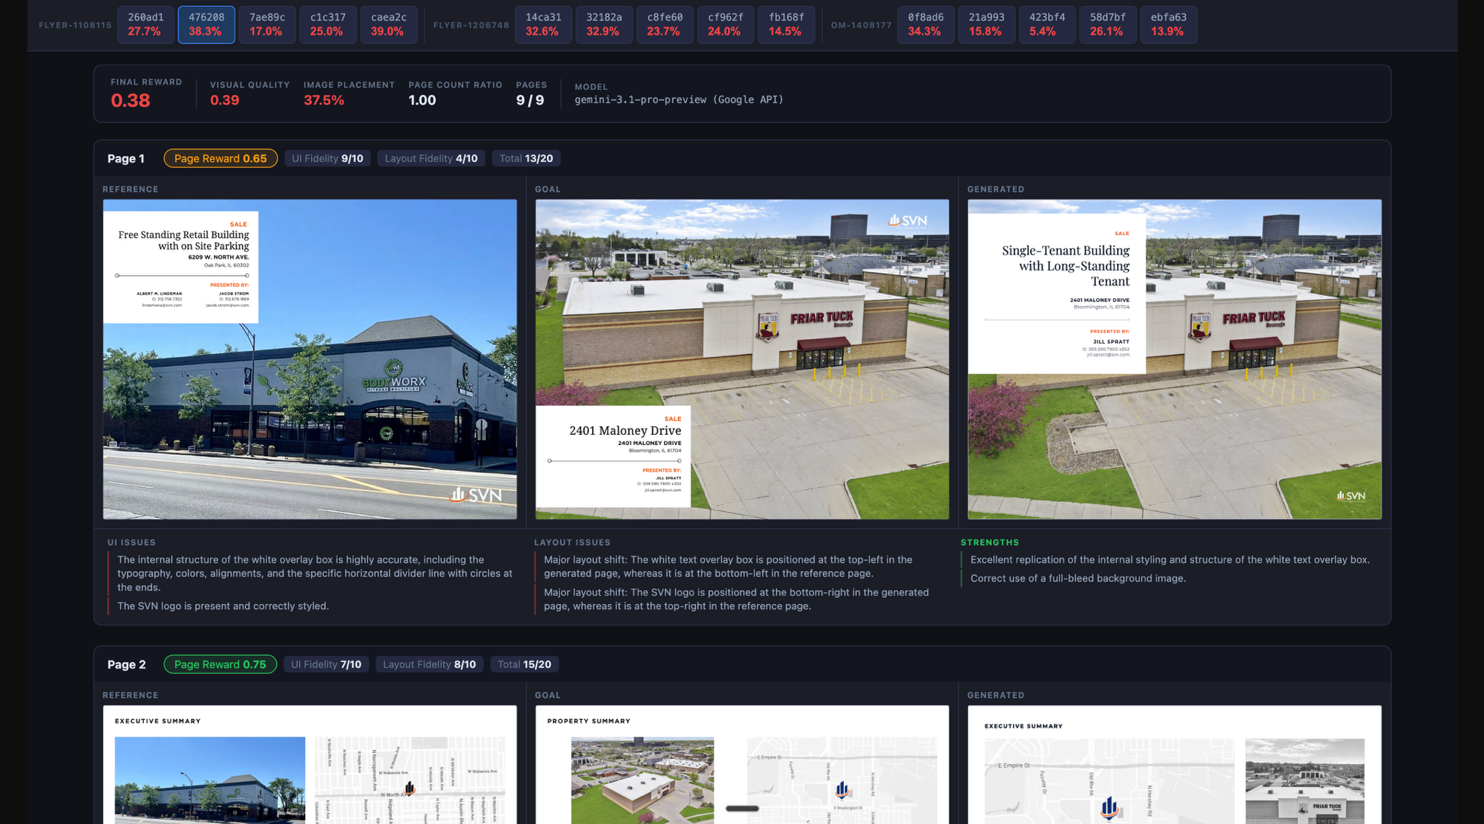
- Model
- Gemini 3.1 Pro Preview
- Final reward
- 0.38
- Visual quality
- 0.39
- Image placement
- 37.5%
- Pages
- 9 / 9
Historical example from the earlier scoring system, preserved from the proposal. The 0.38 reward is one rollout, not an aggregate benchmark result, and is not directly comparable to the current weighted binary-rubric reward.
A document-generation environment
Each run starts with a reference PDF, property data, and a fixed image set in a dedicated workspace. The agent must produce output.html with the requested page structure, using the reference for design and the supplied property materials for facts. This separates visual reconstruction from factual grounding.
I built the HUD harness with model-specific shell and editing tools for Claude, Gemini, and GPT-family agents, plus file inspection and a BuildVu-backed PDF-to-HTML tool. The conversion exposes positioned HTML, SVG, fonts, and assets for inspection. Runs can enable or disable that tool to compare performance with and without structured reference access.
Verification from atomic rubrics
Rubrics are generated ahead of scoring from target-page images and their HTML/SVG conversion artifacts, not adapted to an agent's output. Each check tests one observable condition: an exact financial value, a heading's hierarchy, a map's placement, or a specific visual element. The checks encode the target explicitly, so the scoring judge does not need to see the reference.
The VLM judge evaluates each generated page's screenshot and HTML, returning a yes/no decision and a concrete reason for every check. Partial, ambiguous, or unverifiable matches fail. Render-integrity checks receive only the screenshot, preventing credit for code that looks correct but renders broken images, clipped text, or overlapping elements.
A decomposable reward
Page rewards combine category pass rates: layout and composition 25%, imagery and graphics 25%, typography 20%, render integrity 20%, and text content 10%. Weights are renormalized over the categories present on a page; the final reward is the mean of the weighted page rewards.
Missing required pages fail every associated check. Missing or invalid HTML, or an output with no rendered pages, receives zero. Page-count and image-placement ratios remain diagnostic metrics, but no longer contribute separate terms to the final reward. This replaces the earlier blended visual-score and image-placement formula.
Judge reliability and observability
Evaluation runs separately for each page and rubric category, with up to eight concurrent judge calls. Shorter check lists reduce the tendency to rubber-stamp the end of a long rubric. Responses are validated against the expected schema, check order, and binary answer format, with retries for failed calls.
Each run preserves its objective, workspace manifest, tool-call log, rendered pages, and per-check judgments. HUD traces and local instrumentation capture steps, token usage, and timing; the viewer makes reference, target, and generated pages inspectable side by side. The result is an auditable reward with localized failure explanations, rather than an opaque document-level score.